

RAG vs. fine-tuning is not really a model question. It is a maintenance question. Your model needs company knowledge. You can hand it over at answer time or train it in. One choice stays current. The other freezes a snapshot.
Menlo Ventures’ 2024 enterprise survey found RAG adoption climbed from 31% to 51%. Fine-tuning sat at 9%. Adoption is not the same as fit.
This guide gives you a five-gate test, a cost view, and a hybrid pattern you can apply to your next build.
Key Takeaways
- RAG fixes what the model knows. Fine-tuning fixes how it behaves.
- Changing or citable knowledge points to RAG.
- Strict format, tone, or narrow high-volume tasks point to fine-tuning.
- Update frequency and query volume drive cost more than model size.
- Hybrid systems win when facts and behavior both matter.
The Difference Between RAG and Fine-Tuning
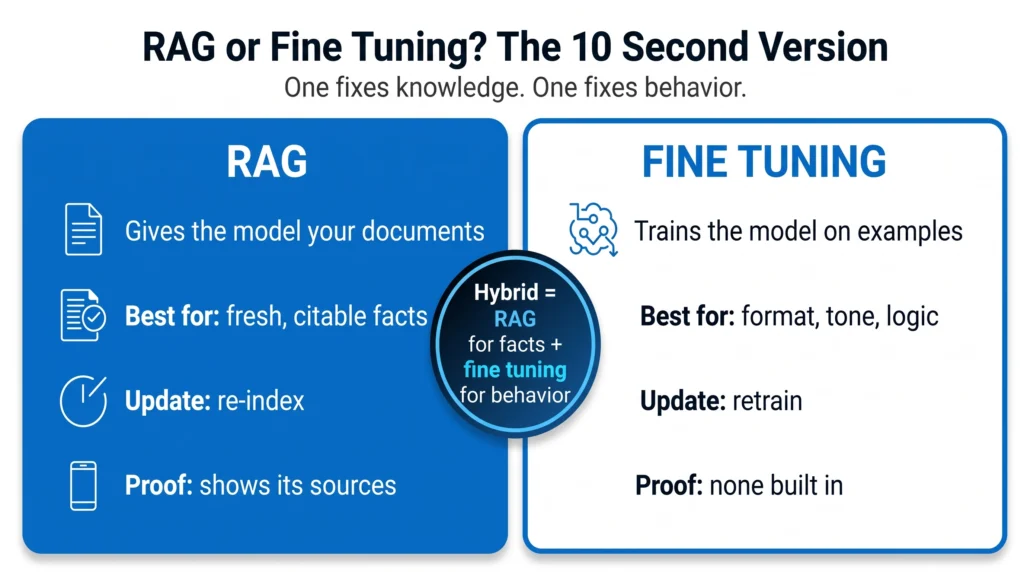
RAG supplies knowledge at answer time. Fine-tuning changes the model itself.
What RAG Does
Retrieval-augmented generation (RAG) retrieves relevant passages from your documents and passes them to the model with the question. Researchers at Facebook AI Research introduced the pattern in 2020.
- The system runs semantic search to find passages that match the meaning of a question.
- A RAG index depends on a vector database and embeddings to match questions to passages.
- Knowledge base grounding ties each answer to a source you can inspect.
RAG at a Glance
- Changes: what the model sees at answer time
- Update speed: as fast as you re-index a document
- Proof: answers can cite the passage used
- Weak spot: poor retrieval produces poor answers
What Fine-Tuning Does
Fine-tuning trains a model further on examples so it learns a style, format, or skill. LoRA and parameter-efficient fine-tuning train small adapter layers instead of every weight. Whatever you train on, training data freshness stops the day training ends.
Fine-tuning at a Glance
- Changes: the model’s weights
- Update speed: needs a new training run
- Proof: no built-in citation of sources
- Weak spot: stale or mislearned facts
When to Use RAG vs Fine-Tuning: The Five Gate Test
Answer five yes or no questions. Each yes points to RAG, fine-tuning, or a deployment rule.
Start with prompt engineering. It costs the least and often closes small gaps. Then run the gates.
- Freshness gate. Does your knowledge change monthly or faster? Yes points to RAG. Large libraries also hit context window limitations, so retrieval selects only what fits.
- Proof gate. Must answers cite a source for audit or trust? Yes points to RAG.
- Behavior gate. Must outputs follow a strict format, tone, or reasoning pattern? Yes points to fine-tuning.
- Volume gate. Is the task narrow, high volume, and latency sensitive? Yes points to fine-tuning.
- Boundary gate. Must data stay inside your own environment? Yes shapes deployment for either pattern.
How to score: Yes answers on both sides mean you need both patterns.

Four Scenarios and the Right Call
These are illustrative builds. Each shows how the gates resolve.
Scenario 1: Internal policy assistant
- Pick: RAG
- Why: Policies change every quarter, and staff need cited answers.
Scenario 2: Claims or ticket triage with a fixed output schema
- Pick: Light fine-tuning
- Why: The format must be exact, and volume is high.
Scenario 3: Customer support with product manuals and brand voice
- Pick: Both
- Why: Manuals change often. Tone must stay consistent.
Scenario 4: Contract review in a regulated firm
- Pick: RAG, with fine-tuning only for clause tagging format
- Why: Every finding must point to a source clause.
Where Each Pattern Fits by Industry
Regulated sectors lean on RAG for facts. They add fine-tuning for strict outputs. These are illustrative patterns, not client results.
Healthcare And Life Sciences
- Lean RAG: clinical guidelines, formularies, and payer policies change often.
- Add fine-tuning for: consistent note structure and coding formats.
- Watch for: every answer needs a traceable source passage.
Financial Services
- Lean RAG: regulations, product terms, and internal policies need citations.
- Add fine-tuning for: report templates and fixed risk language.
- Watch for: audit teams will ask where each answer came from.
Manufacturing and Logistics
- Lean RAG: maintenance manuals, safety procedures, and work instructions.
- Add fine-tuning for: structured work order drafts and equipment codes.
- Watch for: frontline users need fast answers, so measure response time.
Legal And Professional Services
- Lean RAG: case files, clauses, and precedent libraries.
- Add fine-tuning for: clause tagging and house drafting style.
- Watch for: attorneys must verify citations before relying on them.
RAG vs Fine-Tuning for Enterprise Governance and Data Risk
RAG keeps knowledge in an index you control. Fine-tuning bakes it into model weights.
| Risk | RAG | Fine-tuning |
| Deleting a document | Remove it from the index | Retrain to remove it |
| Access control | Enforce per user at retrieval | Hard to enforce after training |
| Audit trail | Log the retrieved passages | Weak source tracing |
| Data exposure | Protect the index and prompts | Training data can surface in outputs |
Regulated teams can run models inside their own data boundary. That means your own AWS or Azure tenancy, or your own hardware.
The RAG vs fine-tuning verdict usually tilts toward RAG when deletion and audit matter.
RAG vs Fine-Tuning Cost Comparison: Where the Money Goes
RAG costs less to start. Fine-tuning can cost less per query at stable, high volume.
Is RAG Cheaper Than Fine-Tuning?
Usually at launch, yes. RAG skips training runs and data labeling. Its cost grows with every query, because retrieved text rides along in each prompt.
RAG adds retrieval steps and longer prompts, which raises inference latency and token cost per query. Fine-tuning front-loads cost into preparation, training, and evaluation.
RAG Cost Lines
- Document ingestion and chunking
- Embedding and index hosting
- Retrieval plus extra prompt tokens on every query
- Ongoing evaluation of retrieval quality
Fine-tuning Cost Lines
- Data curation and labeling
- Training compute
- Retraining when knowledge shifts
- Hosting a custom model
Adapter methods cut training cost sharply. The original LoRA paper reports 10,000 times fewer trainable parameters and 3 times less GPU memory than full tuning of GPT-3 175B.

Count your updates per month and your queries per day. Those two numbers drive the answer. Cost alone rarely settles RAG vs. fine-tuning.
RAG and Fine-Tuning Together: The Hybrid Pattern
RAG owns the facts. Fine-tuning owns the behavior.
Can you use RAG and fine-tuning at the same time?
Yes. A fine-tuned model writes the answer. Retrieval feeds it current passages.
Role split
- RAG handles: policies, manuals, contracts, and anything that changes
- Fine-tuning handles: output schema, brand tone, and reliable tool calling
Test the combination against RAG alone. Extra training does not guarantee extra accuracy.

How to Test Either Pattern Before You Ship
Build a test set before you build the system. Score every change against it.
Build a golden question set
- Collect 50 to 100 real questions from the people who will use the system.
- Write the correct answer and the source passage for each one.
- Include hard cases, such as conflicting documents and outdated policies.
Track Five Metrics
| Metric | What It Tells You | Applies to |
| Retrieval hit rate | Did the right passage come back? | RAG |
| Groundedness | Does the answer match the passage? | RAG |
| Format compliance | Does the output follow your schema? | Fine-tuning |
| Response time | Can users wait for it? | Both |
| Cost per answer | Does the spend hold at scale? | Both |
Run a red team round.
- Ask questions the documents cannot answer. The system should say so.
- Ask for data a user should not see. Permissions must hold.
- Re-test after every document refresh or model update.
Five Mistakes That Sink Enterprise Builds
Most failures come from a short list of avoidable errors. Each one has a clear fix.
Mistake 1: Training a model to store facts
Facts change, and weights do not. Fix: keep facts in an index and train only for behavior.
Mistake 2: Skipping retrieval evaluation
A fluent wrong answer looks like a right one. Fix: score retrieval separately from generation.
Mistake 3: Chunking documents by page count
Page breaks split ideas in half. Fix: chunk by section or topic and keep titles with each chunk.
Mistake 4: Ignoring permissions until launch
Late access control forces a rebuild. Fix: tag documents by role from the first ingestion.
Mistake 5: Fine-tuning on messy examples
The model learns your errors too. Fix: clean, review, and deduplicate examples before training.
What Production Looks Like: The TGS Platform
AI earns trust when its output is validated, logged, and tied to access control. The TGS work centered on video analytics, but the lesson carries over.
See how the same discipline played out in the TGS platform build.
Challenge
- Fragmented HR, safety, and operations processes
- High-volume equipment data with no central view
What we built
- A web-based enterprise platform with a central data warehouse
- Role-based access control for secure, relevant data access
- Video analytics that detect events such as unsecured hopper caps in real time
- Validation, tracking, reporting, and billing built on those events
Result
- Less reliance on manual monitoring
- Traceable, auditable operational records
- Management decisions based on verified data
How Liquid Technologies Chooses the Pattern
Liquid Technologies picks the pattern by testing, not by preference.
Liquid Technologies is an AI native engineering firm based in Houston. Our custom AI development work follows four steps.
Step 1 → Scope. List the questions, the documents, and the output rules.
Step 2 → Test. Run both patterns on your own documents.
Step 3 → Measure. Score accuracy, citations, latency, and cost.
Step 4 → Deploy. Ship inside your own cloud tenancy or on-premises hardware.
A 90 Day Roadmap From Idea to Production
Move in three phases. Each phase ends with a decision, not a deliverable.
Days 1 to 30: Scope and baseline
- Pick one workflow with clear users and a clear success measure.
- Run the five gates and write down the result.
- Build the golden question set and score a baseline.
Days 31 to 60: Build and compare
- Stand up retrieval on a controlled set of documents.
- Test fine-tuning only where the baseline shows behavior gaps.
- Compare both against the same question set.
Days 61 to 90: Harden and release
- Add permissions, logging, and monitoring.
- Run the red team round and fix what breaks.
- Release to a small group, then widen access.
In Conclusion
Models do not fail because teams chose the wrong acronym. They fail because the pattern did not match the knowledge, the behavior, or the boundary. Settling for RAG vs. fine-tuning takes three honest answers. How often does your knowledge change? How strict must the output be? Where may your data live?
Settle RAG vs. fine-tuning on your own data. Liquid Technologies tests both patterns on your documents. Everything runs inside your cloud tenancy or on your own hardware.


